What this AI news story is about
How can a 30B-parameter model activate only 3B parameters per token, and still use the capacity of the larger model? Nemotron 3.5 Lightning illustrates the...
What happened
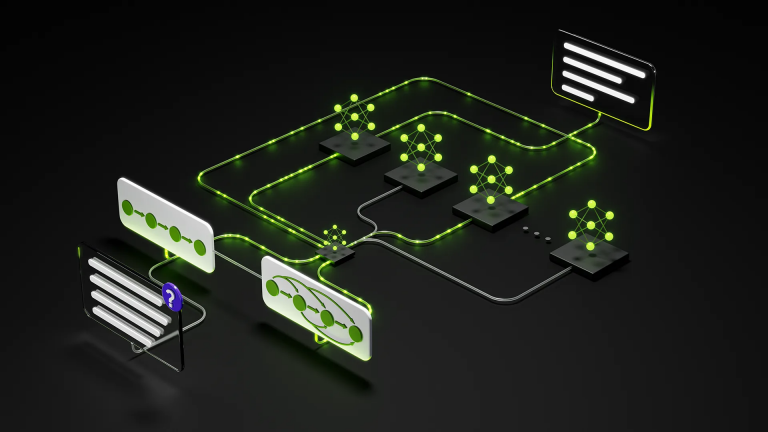
How can a 30B-parameter model activate only 3B parameters per token, and still use the capacity of the larger model? Nemotron 3.5 Lightning illustrates the answer: It uses a Mixture-of-Experts (MoE) architecture that selects only a subset of its parameters for each token. There are two dominant model architectures: Dense model and MoE. How a model organizes its parameters matters as much as…
Source
What readers should know
This TrueVitaHub page summarizes the news information available in the feed. For the complete publisher report, additional reporting, quotes and the latest updates, visit the original source.
Continue with the original source
Read the publisher's complete report for the full story and any subsequent updates.