What this AI news story is about
When an LLM engine process fails, the standard recovery path involves a cold restart. This requires loading weights into HBM from storage, compiling kernels,...
What happened
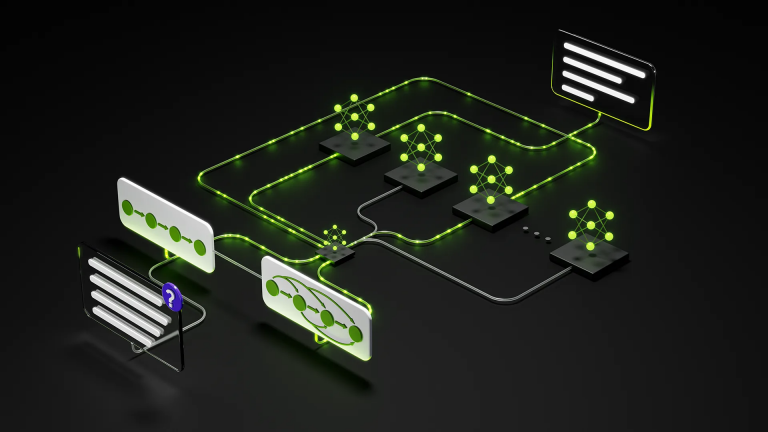
When an LLM engine process fails, the standard recovery path involves a cold restart. This requires loading weights into HBM from storage, compiling kernels, and capturing NVIDIA CUDA graphs. For large models, initialization can take several minutes, during which surviving workers must absorb the displaced traffic. Shadow engine recovery, available as a preview feature in NVIDIA Dynamo…
Source
What readers should know
This TrueVitaHub page summarizes the news information available in the feed. For the complete publisher report, additional reporting, quotes and the latest updates, visit the original source.
Continue with the original source
Read the publisher's complete report for the full story and any subsequent updates.