What this AI news story is about
Mixture of experts (MoE) has become one of the defining architectural trends in large-scale AI model training. DeepSeek, Qwen, and Mixtral are examples of MoE...
What happened
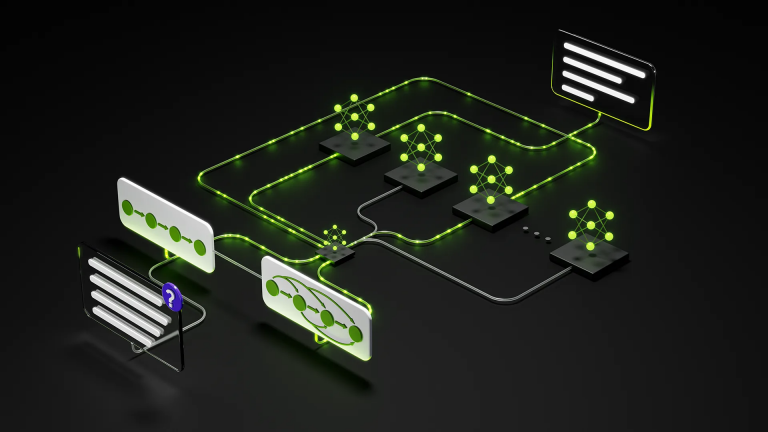
Mixture of experts (MoE) has become one of the defining architectural trends in large-scale AI model training. DeepSeek, Qwen, and Mixtral are examples of MoE models that match or exceed the performance of dense model counterparts at a fraction of the training compute. MoE models provide efficient training through conditional computation. Instead of one dense feed-forward network (FFN) shared…
Source
What readers should know
This TrueVitaHub page summarizes the news information available in the feed. For the complete publisher report, additional reporting, quotes and the latest updates, visit the original source.
Continue with the original source
Read the publisher's complete report for the full story and any subsequent updates.